Cheap is easy to find. Cheap for the way your app actually works takes one more step.
Below is the full top 12, followed by how the ranking changes for different kinds of work.
How We Ranked
- Prices: standard list prices in US dollars per 1 million tokens, read from each provider’s official pricing page and shown on our board on 2026-11-21.
- Blended price: (3 × input + output) ÷ 4. That’s the same formula our board uses, and it assumes you send about three times as many tokens as you get back.
- An everyday comparison: it’s like choosing a phone plan. The cheapest plan depends on whether you mostly call, text or use data, and the cheapest model depends on whether you mostly send text in or get text back.
- Not counted: free tiers, credits, volume deals and quality. A cheap model is only a bargain if its answers are good enough for your task, so test before you switch.
The 12 Cheapest Models by Blended Price
| Rank | Model | Provider | Input | Output | Blended | Open weights |
|---|---|---|---|---|---|---|
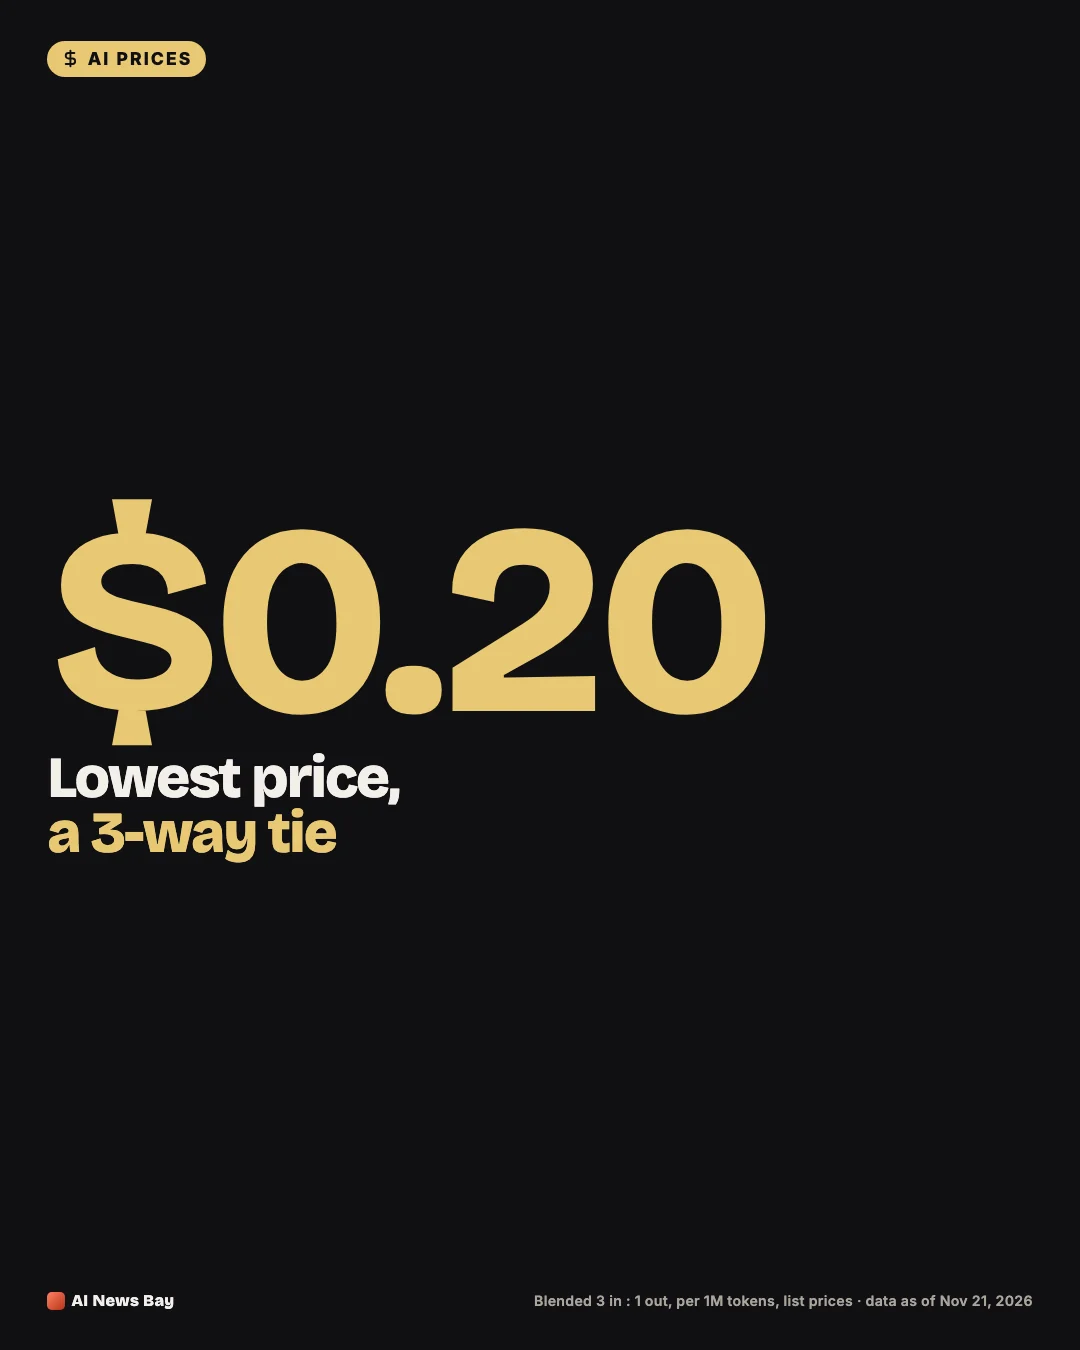
| 1= | Claude Haiku 5.5 | Anthropic | $0.10 | $0.50 | $0.20 | No |
| 1= | GPT-6 Luna | OpenAI | $0.10 | $0.50 | $0.20 | No |
| 1= | Ministral 3 14B | Mistral AI | $0.20 | $0.20 | $0.20 | Yes |
| 4 | GLM-5.3-Flash | Z.ai (Zhipu) | $0.15 | $0.50 | $0.24 | Yes |
| 5= | MiniMax M3.1 Flash | MiniMax | $0.15 | $0.60 | $0.26 | Yes |
| 5= | Mistral Small 4 | Mistral AI | $0.15 | $0.60 | $0.26 | Yes |
| 7= | Codestral 25.08 | Mistral AI | $0.30 | $0.90 | $0.45 | No |
| 7= | GPT-5.6 Luna | OpenAI | $0.20 | $1.20 | $0.45 | No |
| 9= | DeepSeek V4.1 Flash | DeepSeek | $0.30 | $1.20 | $0.53 | Yes |
| 9= | MiniMax M3 | MiniMax | $0.30 | $1.20 | $0.53 | Yes |
| 11 | GLM-5.3-FlashX | Z.ai (Zhipu) | $0.37 | $1.25 | $0.59 | No |
| 12 | Gemini 3.5 Flash-Lite | $0.30 | $2.50 | $0.85 | No |
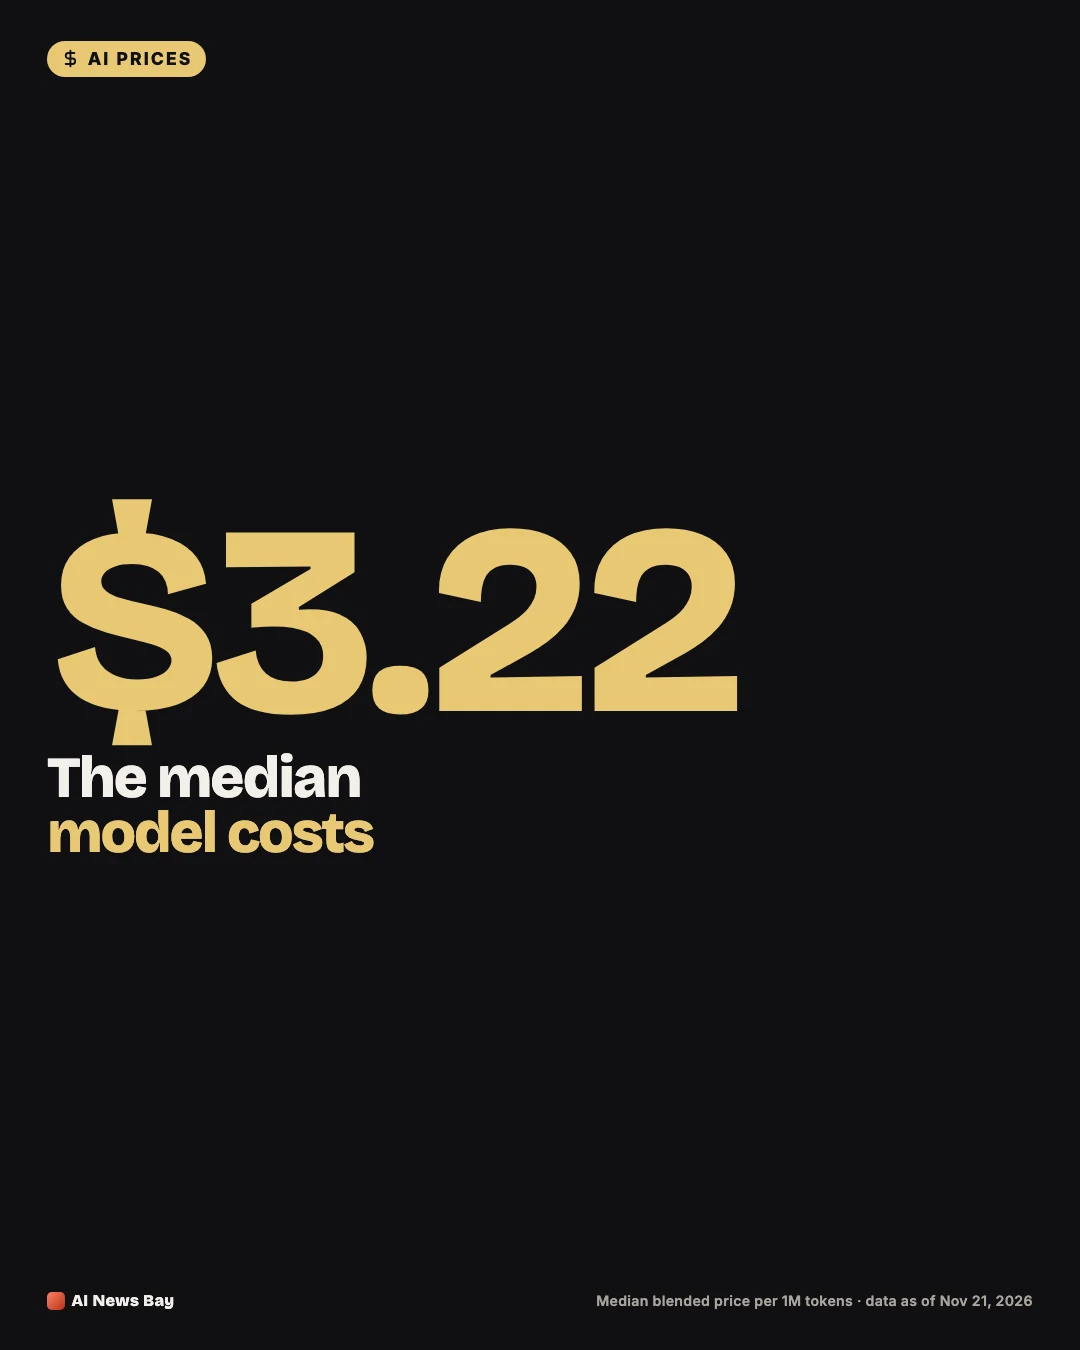
All 12 cost less than a dollar per million blended tokens. The median model on our board costs $3.22 blended. Six of the 12 are open-weight (corrected on 2026-11-22: GLM-5.3-FlashX’s weights aren’t published), and every one of the nine providers on our board except xAI and Moonshot AI has at least one model on this list.
Did you know? Ministral 3 14B charges the same $0.20 per 1M tokens for output as for input. Across our board, output usually costs about five times as much.
If You Send Long Prompts
When most of your tokens are input (long documents, big system prompts, retrieval), input price matters most. Weighting input ten to one, the order becomes:
- Claude Haiku 5.5 and GPT-6 Luna: $0.14
- GLM-5.3-Flash: $0.18
- MiniMax M3.1 Flash and Mistral Small 4: $0.19
- Ministral 3 14B: $0.20
Watch the size limits, though. Claude Haiku 5.5’s input price rises from $0.10 to $0.50 per 1M tokens for prompts over 100,000 tokens. GPT-6 Luna’s rises from $0.10 to $0.20 above 272,000 tokens. Ministral 3 14B and Mistral Small 4 list a context window of 256,000 tokens on our board. Most others in the top 12 list about 1 million.
If Your App Writes Long Answers
When output dominates (drafting, long reports, code generation), Ministral 3 14B pulls clearly ahead, because it charges the same $0.20 for output as for input. Weighting output two to one:
- Ministral 3 14B: $0.20
- Claude Haiku 5.5 and GPT-6 Luna: $0.37
- GLM-5.3-Flash: $0.38
- MiniMax M3.1 Flash and Mistral Small 4: $0.45
If the Work Can Wait: Batch and Off-Peak
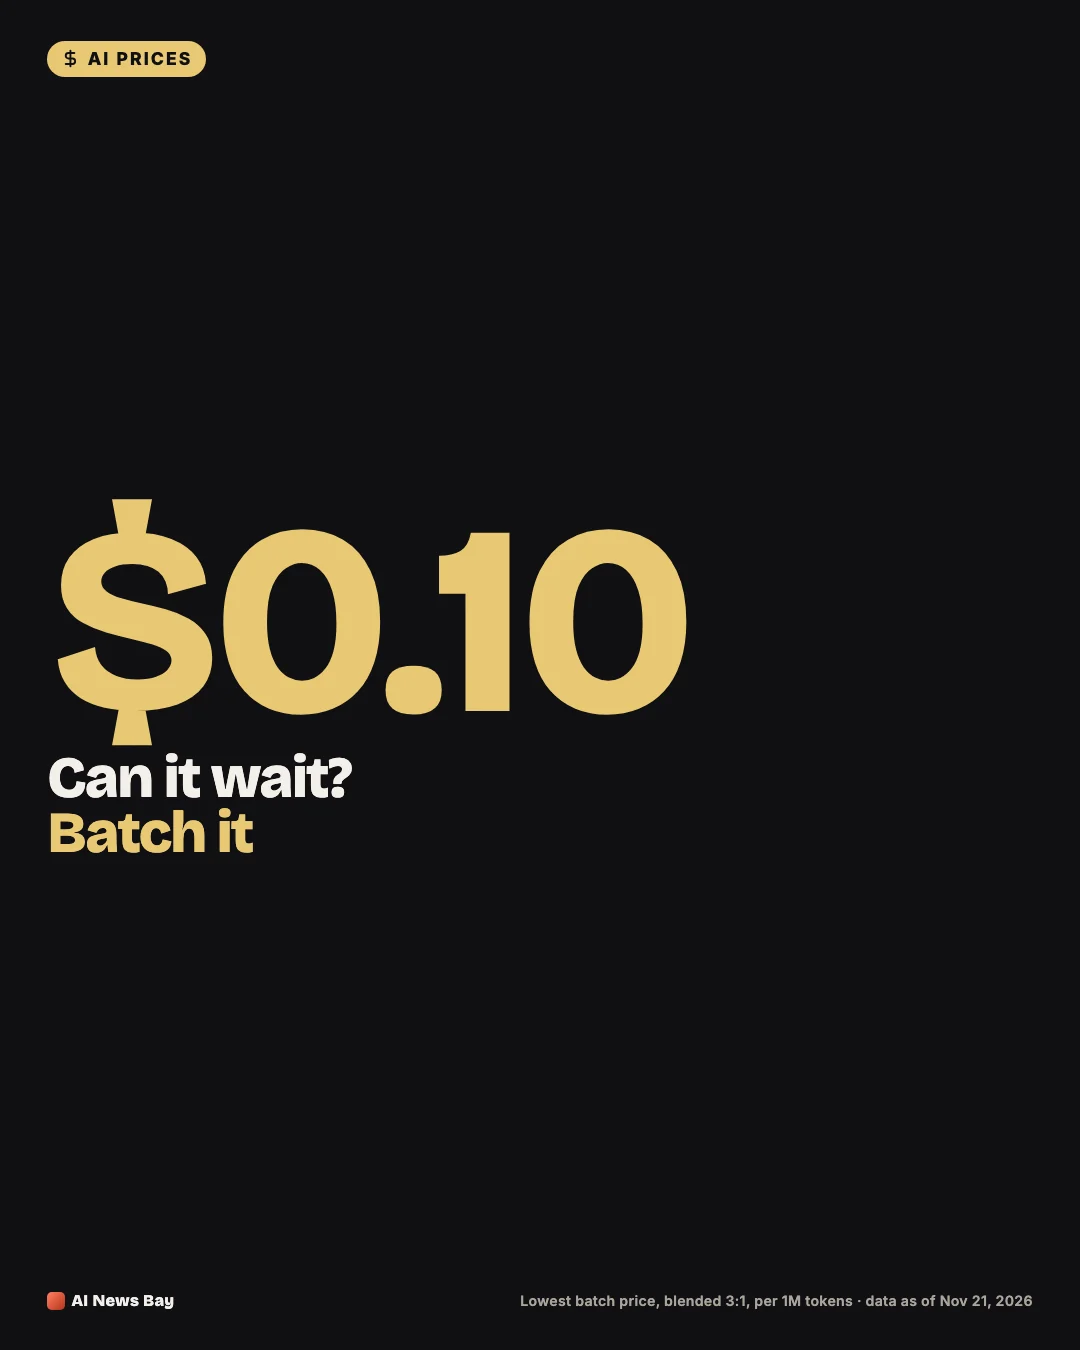
Several providers price non-urgent work lower, and that changes the ranking again. Using the batch or off-peak prices listed on our board (blended 3:1):
| Model | Discount type | Blended price |
|---|---|---|
| Claude Haiku 5.5 | Batch | $0.10 |
| GPT-6 Luna | Batch | $0.10 |
| Ministral 3 14B | Batch | $0.10 |
| Mistral Small 4 | Batch | $0.13 |
| Codestral 25.08 | Batch | $0.23 |
| GPT-5.6 Luna | Batch | $0.23 |
| DeepSeek V4.1 Flash | Off-peak | $0.26 |
DeepSeek’s pricing page says off-peak rates are half of peak rates, and lists its peak hours in UTC. GLM-5.3-Flash and MiniMax M3.1 Flash list no batch price on our board, so they drop down this table.
If You Repeat the Same Prompt: Caching
If many requests share a long fixed beginning, cached-input prices matter. Among the top 12:
- Claude Haiku 5.5 and GPT-6 Luna list a cached-input price of $0.01 per 1M tokens.
- DeepSeek V4.1 Flash lists $0.006.
- Codestral 25.08, Ministral 3 14B and Mistral Small 4 list no cached price on our board.
So for a chatbot with a large fixed system prompt, the lowest-cost model can be a different one again.
How to Pick from This List
- Match the shape of your traffic. Mostly input, mostly output, or batch: use the matching ranking above.
- Check the context limits if your prompts are long.
- Shortlist three models from different providers and run the same 30–50 real requests through each.
- Price your real token counts with the calculator on our price board, or follow the worked examples in What Does One AI API Request Cost?.
- Combine savings: our guide How LLM API Pricing Works explains how tiers, caching and batch discounts apply.
For chat use in particular, our collection of cheap models for a chatbot is a good starting point.
What This Means for You
- Developers: pick the ranking that matches your traffic shape, then run the same 30–50 requests through the top three.
- Founders and team leads: all twelve models here cost under $1 per million blended tokens; the bigger question is which one is good enough for your users.
- Curious beginners: these are prices for developers using AI through code. Chat apps you use in a browser are priced differently.
Myth vs Fact
| Myth | Fact |
|---|---|
| The lowest-priced model is the same for every app | It depends on your mix of input, output, batch and caching |
| Batch pricing is only for big companies | Anyone can use it for work that can wait, often at half price |
Copy-Ready Shortlist Template
- Traffic shape (input-heavy / output-heavy / batch / cached): ____
- Model 1 and its price for that shape: ____
- Model 2 and its price for that shape: ____
- Model 3 and its price for that shape: ____
- Quality on my 30–50 test requests: ____
Is most of your traffic questions in, or long answers out?
Bottom Line
On 2026-11-21, the cheapest LLM APIs on our board were Claude Haiku 5.5, GPT-6 Luna and Ministral 3 14B, each at $0.20 blended per 1M tokens. Nine more models stayed under $1. The right choice depends on your traffic: low input prices suit long prompts, Ministral 3 14B suits long answers, and batch or off-peak pricing halves many of these costs for work that can wait. Prices change, so check the live price board before you commit.
Next, see What Does One AI API Request Cost? for worked examples. Want these updates by email? Sign up here, or follow new guides and data stories through our RSS feed.